FAQs
No items found.

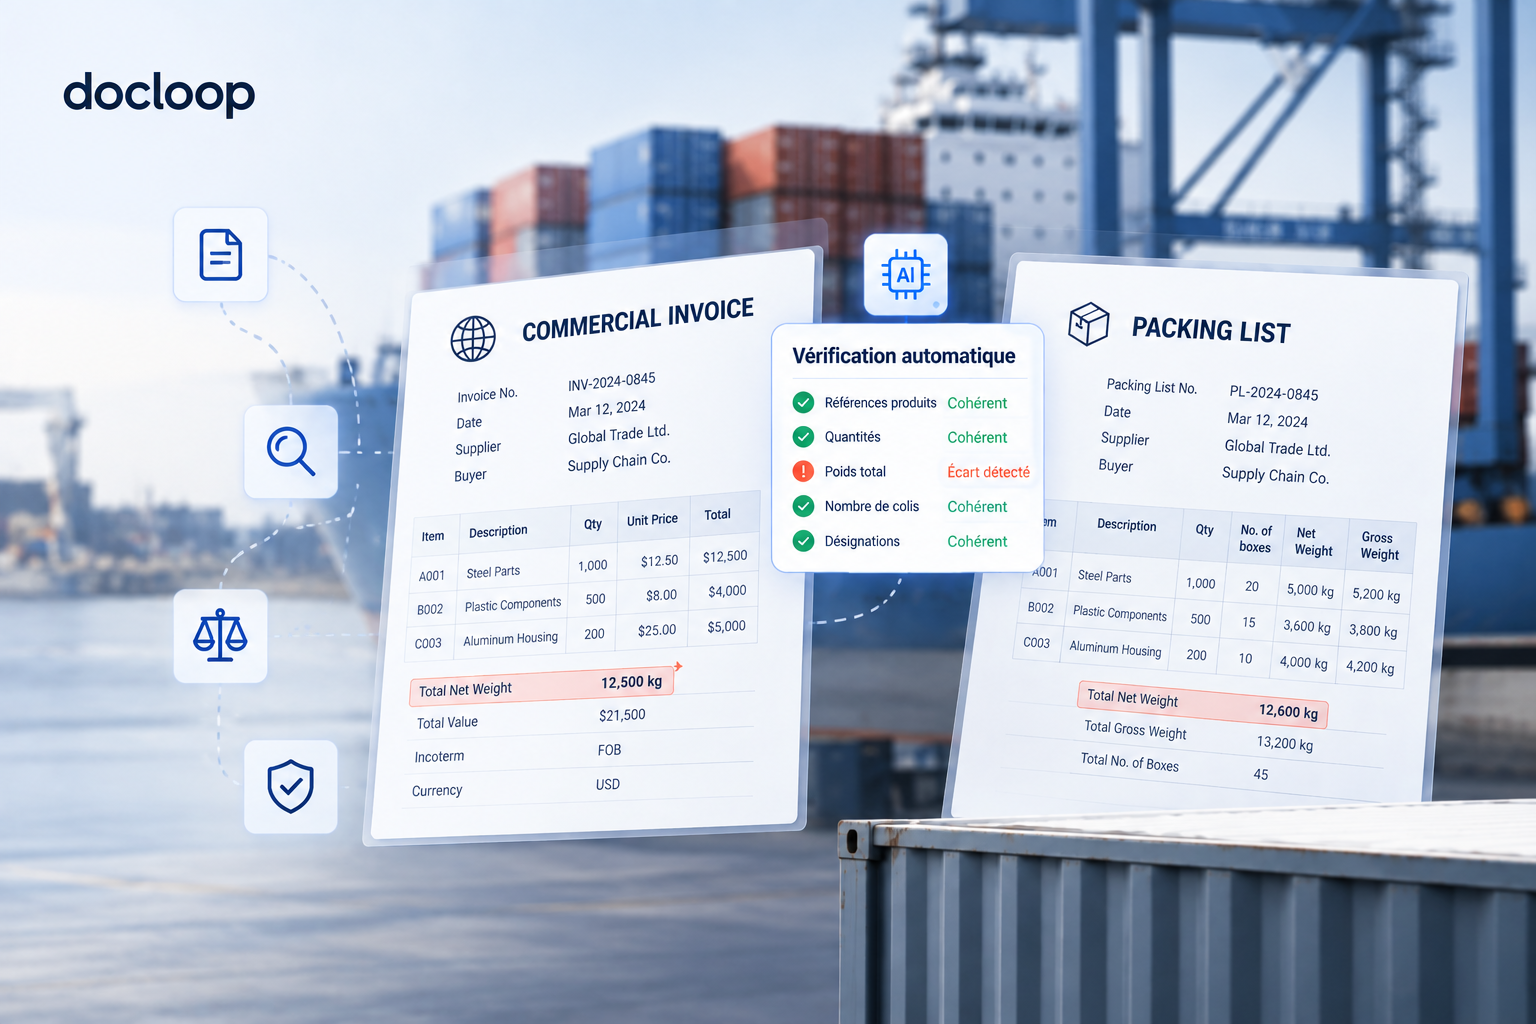
A commercial invoice lists 12,500 kg.
The packing list lists 12,600 kg.
And the bill of lading lists 12,850 kg.
However, all three documents are perfectly legible. The data was extracted correctly. There were no OCR issues and no apparent reading errors.
So, what's the problem?
The documents do not tell exactly the same story.
This is a common situation in international transportation and trade. A single shipment is documented by several different documents: commercial invoice, packing list, bill of lading, purchase order, customs documents, certificate of origin, and freight invoice. Each document contains some of the information required for the transaction.
The real challenge isn't just being able to read these documents. It's being able to automatically answer a much more important question:
Does the information in these documents refer to the same transaction?
That is where the document reconciliation begins.
Before discussing automation, we need to distinguish between the roles of these two documents.
These documents contain some common information, but they are not meant to be identical.
An invoice and a packing list must be consistent in the information they have in common; they do not necessarily have to contain the same data.
The first principle of automatic verification is to determine which data points actually need to match.
At first glance, the problem seems simple. All you would have to do is take the information from the invoice and the packing list, and then check whether the values match. But this approach quickly reaches its limits.
A difference isn't necessarily a mistake
Let's imagine:
Invoice: 1,000 units
; Packing list: 960 units
A comparison system immediately detects any discrepancies.
But if the order is for 960 units, the situation is perfectly understandable.
These may include:
The system should avoid automatically treating every discrepancy as an error.
He must try to understand the discrepancy.
The comparison raises a simple question:
Are the two values the same?
Reconciliation raises a business-related question:
Do these two pieces of information describe the same reality, and if they differ, why?
This distinction is fundamental.
Document reconciliation involves comparing the information in multiple documents to identify inconsistencies before they become operational problems.
Comparing helps us identify a difference. Reconciling helps us understand that difference.
Reliable verification involves several steps. The goal is not simply to compare two PDF files, but to transform the information in the documents into verifiable data.
The system begins by recognizing the documents in the folder:
This step ensures that each file is not treated as a standalone document. An international shipment consists of many items, received at different times and from different sources.
The documentary AI excerpt:
This is the traditional role ofOCR and, above all, of Intelligent Document Processing.
But extraction is just the starting point.
Information extracted automatically is not necessarily reliable in its context.
An invoice can very well show “12,500 kg” and a packing list “12,600 kg” without there having been a reading error.
The issue, therefore, is no longer what is written, but whether that information is consistent with the other information in the file.
Before comparing the data, you need to be able to handle:
This step prevents the creation of artificial anomalies. For example, directly comparing a quantity expressed in metric tons with another expressed in kilograms could result in a false discrepancy. The automation process must first ensure that comparable information is being compared.
The same item may be listed differently on an invoice and a packing list. The system must identify which items actually correspond.
This is particularly important when documents contain multiple references or multiple levels of packaging.
An invoice may include:
Product A — 500 units
whereas the packing list lists:
Product A — boxes 1 through 10 — 500 units.
The structure is different, but the information refers to the same product.
Once the data has been identified, standardized, and reconciled, the system can perform the checks.
For example:
Quantities
Invoice: 1,000,
Packing list: 1,000
→ Consistent
References
Invoice: SKU-4587
Packing list: SKU-4587
→ Consistent
Weight
Invoice: 12,500 kg
Packing list: 12,600 kg
→ Discrepancy detected
Package
Invoice: 50 cartons
Packing list: 52 cartons
→ Discrepancy to be analyzed
But automation shouldn't stop at this stage.
A discrepancy can be:
The quality of automation therefore depends as much on the classification of anomalies as on their detection.
Once the discrepancy has been identified, the system can:
The goal is not to replace the expert, but to spare them the trouble of manually searching for anomalies throughout the entire file.
A comparison of the invoice and the packing list can reveal several types of discrepancies.
Invoice: 1,000 units
Packing list: 960 units
→ Discrepancy to be analyzed.
The system searches for the quantity specified in the order or in other documents in the file.
Invoice: SKU-4587
Packing list: SKU-4589
→ The reference does not match.
This indicates a data entry error, an incorrect reference, or a change that has not been updated.
The two documents use different descriptions for the same commodity. The inspection must therefore be able to distinguish between a difference in description and an actual difference in the product.
Invoice: 12,500 kg
Packing list: 12,600 kg
→ Discrepancy detected.
But it is also important to verify the nature of the data:
An effective check must therefore take into account the type of weight being compared.
Invoice: 50 cartons
Packing list: 52 cartons
→ Discrepancy to be checked.
Once again, the context may explain the difference.
Consistency isn't just about contradictory data.
A document may be incomplete:
Document verification must therefore ensure both consistency and completeness.
This is probably the most important point for understanding the difference between a basic document review and a more advanced approach.
Let's talk about weight.
The invoice may include:
Net weight: 12,500 kg
The packing list:
Net weight: 12,500 kg
Gross weight: 12,600 kg
There is no inconsistency.
The two documents simply do not contain exactly the same information.
The same logic applies to quantities.
Invoice: 1,000 units
Packing list: 960 units
Order: 960 units
The system must be able to recognize that a discrepancy between the invoice and the packing list warrants verification, but that the order provides essential context.
That is why the goal is not to "match" two documents.
The goal is to verify that the information describing the same transaction is consistent.
It is helpful to distinguish between several levels.
But reconciliation makes it possible to cross-check information. This is an important distinction in document automation.
A solution can perfectly extract data from an invoice and a packing list without necessarily knowing whether that data is consistent between the two documents.
A piece of data may be extracted perfectly and yet be inconsistent with the rest of the file.
An invoice and a packing list almost never go together. An international transaction also requires:
Each document contains a portion of the information. The problem arises when these different sources no longer match. That is why verification must no longer focus solely on:
Invoice ↔ Packing List
but gradually over:
Invoice ↔ Packing List ↔ B/L ↔ Order ↔ Operational Data
This is how we move from a document to a file.
A transportation case is evolving.
New documents are arriving. An invoice is corrected. A packing list is replaced. A validation is performed. An operational event may change the interpretation of a piece of data.
Treating each document separately means losing some of that context.
The file must contain:
Auditing is no longer a one-time activity. It becomes an ongoing review of documentation.
Good automation shouldn't just display: "Mismatch"
It must make the anomaly understandable and actionable.
For example:
Invoice: 1,000 units
Packing list
,960 units
Order: 960 units
Analysis
Discrepancy between the invoice and the packing list. The order matches the packing list.
Recommended action
: Check whether the invoice needs to be corrected.
This gives the operator immediate access to the information needed to make a decision.
This approach is important in complex document-processing workflows: AI automates checks and focuses human intervention on exceptions, rather than seeking to systematically replace domain expertise.
Traceability is also essential: it must be possible to trace the source document, the relevant data, the detected anomaly, the control applied, and the decision made.
The file is not static. A new document is added after the invoice and the packing list. A new version can replace an old one. Information is corrected. A validation can change the status of a check.
That is why document reconciliation should not be viewed as a one-time, ad hoc verification. It can become an ongoing review of the file.
Ultimately, this is where the difference lies between simple document automation and a truly business-oriented approach.
Invoice: 1,000,
Packing list: 960,
s → Difference.
Invoice: 1,000,
Packing list: 960,
Order: 960,
→ Discrepancy identified and contextualized.
Discrepancy analyzed → reference source identified → recommended action → decision documented.
This progression is at the heart of the Docloop approach. Making documents reliable is not just about extracting more data. It involves transforming scattered documents into verified, consistent information that can be directly used in business processes.
Automating the verification process between a commercial invoice and a packing list seems simple. But a truly reliable verification process must go much further:
Identify documents → extract data → standardize → match → verify → detect discrepancies → contextualize them → recommend an action.
The difference is significant. A comparison seeks out a difference.
Reconciliation seeks to understand this difference.
And document reliability goes even further: it ensures that the information used to manage a logistics operation is consistent, complete, and actionable.
That is why true document automation is no longer just about transferring information from a PDF to a TMS or an ERP system.
It involves verifying that this information is reliable before passing it on in the process.