FAQs
No items found.

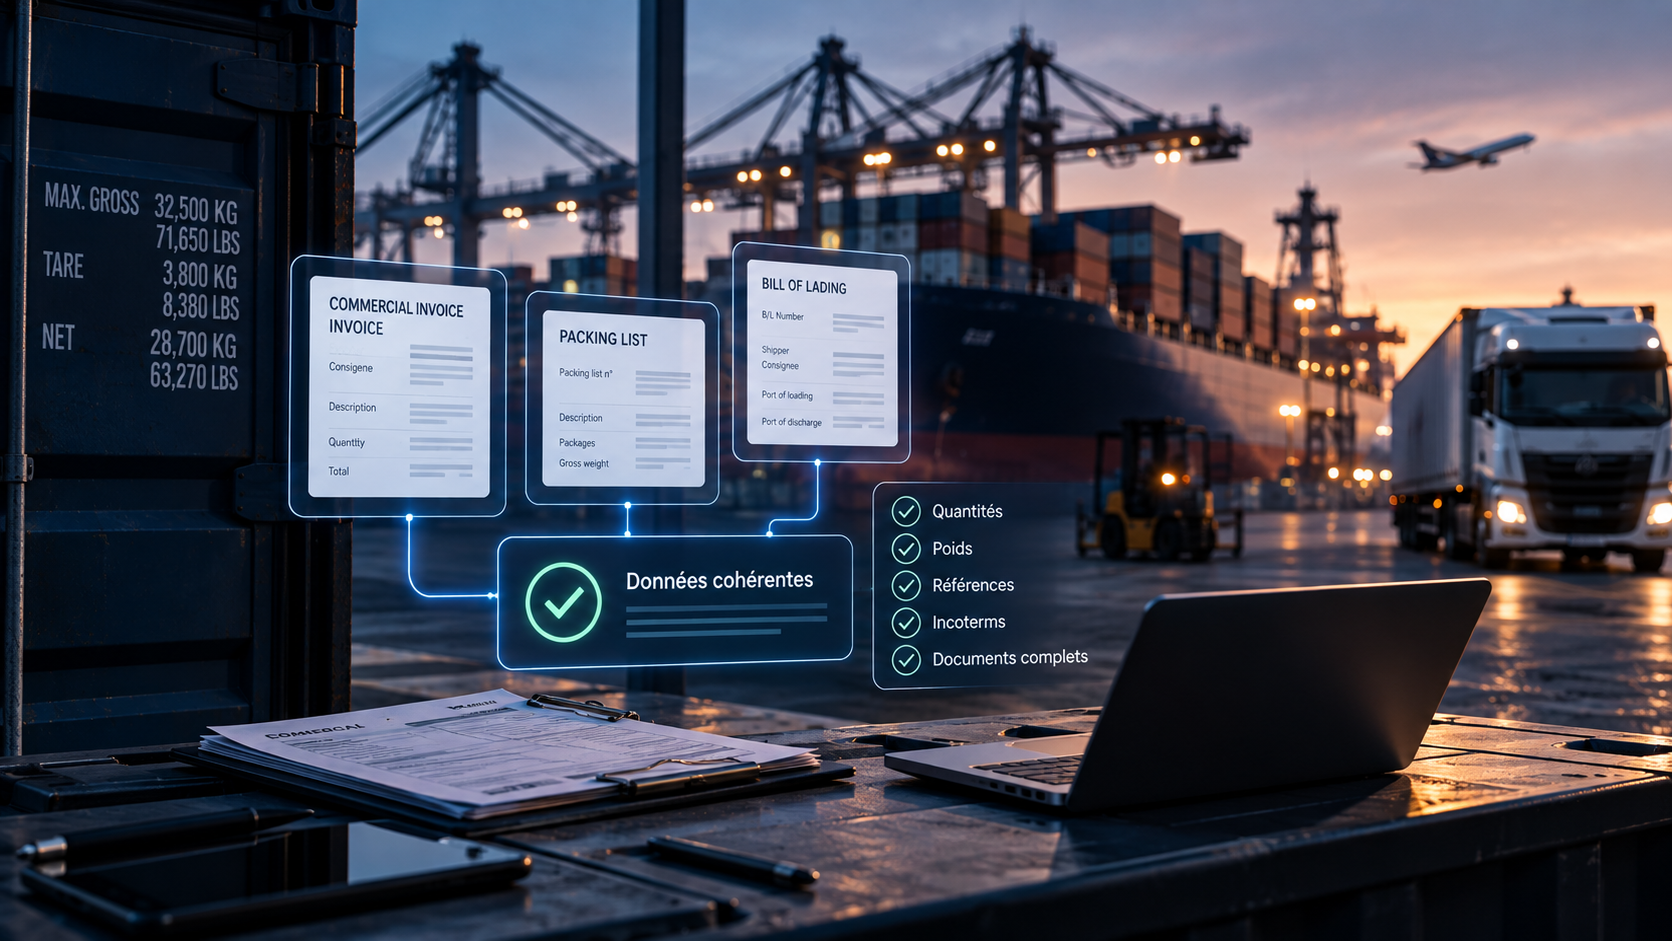
A mistyped part number, a reversed quantity, or an incorrect weight may seem like simple administrative errors. In a logistics operation, however, these errors propagate across multiple systems and cause delays, billing errors, or difficulties during customs clearance.
This issue is particularly significant when data flows between emails, PDFs, shipping documents, TMS, ERP, WMS, and customs tools. The same information may be entered multiple times, by multiple people, into multiple systems.
The first solution is to reduce manual data entry through automation.
But automating data entry alone does not guarantee data reliability.
Information may be correctly extracted from a document but still be inconsistent with other information in the file. To truly secure operations, we must go a step further: reduce data re-entry, validate the data, and verify its consistency across the entire shipping file.
Logistics operations rely on a large amount of information that must flow quickly between multiple parties and systems.
An international expedition may involve, among other things:
These documents are received via email as PDFs, through a partner portal, or directly from a business system.
The same information appears in several places: references, quantities, weights, values, currencies, dates, addresses, or Incoterms.
When this data is re-entered into multiple tools, each new entry creates an additional risk of error.
The errors relate to:
These errors do not necessarily result from a lack of attention. They are often linked to the proliferation of documents, tools, and manual tasks.
This is one of the most important factors when seeking to improve the reliability of logistics operations.
Not all data errors are caused by human error.
An operator reads "12,500 kg" on a document and enters "12,050 kg" into the system.
The information in the document was correct, but it was transcribed incorrectly.
An automated system analyzes a document but misinterprets a piece of information.
Manual data entry is disappearing, but the risk of error does not necessarily disappear along with it.
It's a different situation.
Each piece of data may have been entered or extracted correctly, but the information in several documents does not match.
Let's take an example:
The three values may have been extracted correctly.
However, there is an anomaly in the file.
So the question is no longer just:
What is in this document?
It becomes:
Is the information throughout the entire file consistent?
That is precisely the purpose of document reconciliation: to compare information from multiple sources in order to identify discrepancies and anomalies. This approach goes beyond simply extracting data from a single document.
Reducing errors requires taking action throughout the entire information flow, not just at the point of data entry.
The first step is to avoid manually copying information that is already included in an email or document.
Automatic extraction allows you to:
The goal is simple: capture information once and reuse it as much as possible.
Standardization also makes it easier to detect errors.
It covers:
The more structured the data is, the easier it becomes to automatically verify its validity and consistency.
Data that is extracted automatically should not necessarily be considered reliable by default.
It can be evaluated based on several criteria:
The goal is not only to extract data, but to determine whether it can actually be used in the operational process.
It is often at this stage that the most difficult-to-detect anomalies appear.
A commercial invoice can be compared to a packing list. A shipping invoice can be likened to a quotation. The data in a declaration can be compared to the supporting documents.
The system can then automatically search for:
The process, therefore, no longer ends with extraction:
Extract → verify → reconcile → detect discrepancies → alert.
Automation eliminates many repetitive tasks. But it should not be confused with reliability.
Let's imagine that an invoice is automatically analyzed, its data is extracted, and then transmitted directly to the TMS.
The process is quick.
However, if the quantity listed on the invoice differs from that on the packing list, or if the weight does not match the bill of lading, the system has simply transmitted unverified information more quickly.
That is why the real goal is not just:
automate data entry
but:
Automate data entry while ensuring the reliability of the information.
This distinction is particularly important when multiple systems are interconnected. Incorrect data can be automatically propagated to multiple tools, making it more difficult to identify and correct.
A logistics operation is almost never based on a single document.
The documents are arriving gradually. A shipping order may arrive first, followed by an invoice, a packing list, a shipping document, and then additional regulatory documents.
Some parts can also be repaired or replaced.
The system must maintain the context of the operation as new information becomes available.
That is why the transport file provides a more relevant basis for analysis than the document on its own.
The document is then no longer considered to be independent information.
The file becomes the object to be understood, controlled, and made reliable.
Once the information has been gathered in the context of the case, many checks can be automated.
The system can compare:
The information contained in a bill of lading, a CMR, or an AWB is compared with the other data available in the file.
Inspections may include, among other things:
The invoiced amounts are compared with the applicable rate schedules or available quotes to identify any discrepancies.
These checks help detect anomalies before they become operational errors. In particular, Docloop uses data reconciliation from multiple sources to identify inconsistencies and perform consistency and compliance checks.
Reducing data entry errors does not necessarily mean eliminating human involvement.
Automation handles repetitive tasks:
The operator intervenes when information is uncertain or when a business decision is required.
The goal is to focus human expertise on exceptions, rather than on the systematic transcription of the same information.
The issue of data entry errors ultimately leads to a broader problem.
It is not enough to simply eliminate manual data entry. We must ensure that the information entering the logistics process is reliable, consistent, complete, and actionable.
This involves gradually transitioning from:
enter → verify
toward a more comprehensive approach:
capture → understand → verify → reconcile → detect → recommend.
This development is also changing the way we think about document automation.
The document is no longer necessarily the central unit of processing. The system must be able to understand the relationships between multiple documents, maintain the context of the operation, and identify anomalies that arise at the file level.
This is the direction in which a new generation of document-based AI is developing: AI capable not only of reading and extracting information, but also of analyzing the case, verifying its consistency, and recommending the necessary actions, subject to the operator’s approval